
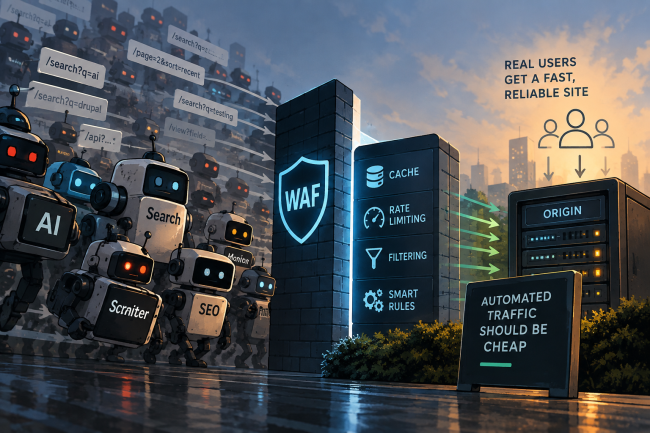
AI companies need enormous amounts of content for training, retrieval, search, and real-time answers. That has created another class of crawlers alongside traditional search-engine bots. And unlike the relatively predictable crawl patterns we've spent years optimizing websites around, AI-related traffic isn't always as easy to identify or control. There are well-known AI crawlers that identify themselves, but there are also third-party data collectors, scraping services, and automated agents that may not.
The distinction between various types of crawlers matters less once you're looking at the problem from the origin server.
A legitimate crawler, an AI scraper, and a badly behaved bot can all create the same basic problem: they're consuming resources that were primarily sized for actual users.
And the cost of a request isn't always equal.
Recently, I’ve been dealing with sites where automated traffic wasn’t just showing up in analytics, it was creating measurable load at the application layer. Search endpoints are particularly attractive because a single request can trigger database queries, search infrastructure, rendering, and caching behavior. A bot that discovers a search form can generate thousands of combinations of keywords, filters, pagination, and query parameters. Each URL may look unique to the caching layer while ultimately asking the application to do expensive work over and over again.
The bot doesn't have to be malicious. An AI crawler trying to collect public information may be doing exactly what it was designed to do while still creating something that, from an infrastructure perspective, looks remarkably similar to a denial-of-service attack.
This is also why simply looking at overall traffic numbers can be misleading. Ten thousand requests for cached pages may barely touch the origin. A much smaller number of requests against an expensive, poorly cached search endpoint can cause a noticeable performance problem.
The obvious response is to put a Web Application Firewall (WAF) in front of it and start rate limiting.
Rate limiting works. Until it doesn’t.
Back to topRate limiting is easy. Good rate limiting is not.
A rule like “allow 20 requests per minute per IP” sounds perfectly reasonable. For obviously abusive traffic, it often is.
The problem is that an IP address does not necessarily represent one person.
Corporate networks, government agencies, schools, VPNs, mobile carriers, and other shared networks can put hundreds of legitimate users behind the same public IP. Suddenly your WAF sees what looks like an aggressive bot when it is actually full of people trying to use your website.
This becomes particularly noticeable during an incident. Users get an error, refresh, try again, open another tab, or tell coworkers to see whether the site works for them. The protective rule can then amplify the problem by interpreting those retries as additional abusive traffic.
That’s why I’ve become increasingly wary of deploying aggressive rate limits and calling the problem solved.
A WAF rule should be treated as something that needs tuning, not a switch you turn on.
Back to topStart with the expensive endpoints
There usually isn’t a good reason to apply the same limits everywhere.
On a Drupal site, for example, I’m much more interested in traffic hitting things like search pages, exposed Views, AJAX endpoints, file delivery controllers, login forms, APIs, or anything else capable of generating meaningful backend work.
A request for a cached CSS file and a request that executes a complex Search API query are technically both HTTP requests, but operationally they are very different.
Protect the expensive paths first.
That also makes your rules easier to reason about. If the /search path suddenly receives thousands of requests containing unique query strings, you have a much clearer signal than simply knowing that an IP made a lot of requests to the site.
Look at behavior, not just volume
Request volume is useful, but it is a crude way to identify bots.
Better signals include request frequency, repeated searches, rapidly changing query strings, sequential crawling, unusual user agents, missing browser headers, suspicious query parameters, repeated cache misses, and traffic patterns that a human realistically could not generate.
None of these signals are perfect by itself. The goal should be to combine signals until you are reasonably confident that you are looking at automation rather than trying to define a magical requests-per-minute number that separates humans from bots.
Back to topKnow what your users look like before you block them
One of the most useful things you can do before tightening WAF rules is understanding how legitimate users reach the site.
- Are employees behind a VPN?
- Does an entire organization exit through a small number of public IP addresses?
- Are monitoring systems regularly requesting certain pages?
- Are accessibility scanners, search engines, integrations, or other legitimate automated systems hitting endpoints that look suspicious?
If a known organization is behind a predictable subnet, that traffic can be handled differently. But whitelisting should be deliberate. You don't want to solve one overly broad rule by creating an equally broad hole in it.
Logs matter here.
Before increasing infrastructure because a site appears to be overwhelmed, I want to know who is generating the traffic, which URLs they are requesting, how often they are requesting them, whether those requests are cache hits or misses, and how much work is reaching the origin.
Otherwise, you're just buying more capacity for the bots.
Back to topA WAF isn't your only defense
Not every project has Cloudflare, Fastly, Akamai, or another sophisticated edge security layer available.
Even without these tools, you can still make bot traffic considerably less painful.
The first defense is caching.
If anonymous users receive identical content, let your caching layer absorb as much of that traffic as possible. A bot hitting cached content is mostly an annoyance. A bot repeatedly forcing Drupal, PHP, the database, and Solr to generate a response is a capacity problem.
That means reviewing cache headers, query-string handling, cache variation, CDN configuration, and endpoints that unexpectedly return private or no-store.
Application-level rate limiting is another option. A reverse proxy such as Nginx or Apache can also limit requests to expensive paths before they reach PHP.
Search deserves special attention. Limit unreasonable query lengths, reject obviously malformed requests, avoid caching useless tracking parameters as unique pages, and make sure arbitrary combinations of parameters can't create an unlimited number of expensive cache variations.
For endpoints that don't need anonymous access, don't expose them anonymously.
And don't underestimate basic robots controls. robots.txt will not stop malicious bots, because malicious bots don't care what it says. But preventing cooperative crawlers from wasting resources on infinite search combinations, filtered Views, and other low-value URLs can still remove a surprising amount of unnecessary traffic.
Don't accidentally DDoS yourself with protection
This part often gets overlooked. Every protective measure changes the behavior of the system.
A WAF rule can block legitimate users. A CAPTCHA can destroy accessibility or usability. An overly broad cache bypass can push traffic back to the origin. A badly configured bot rule can block integrations. An enormous whitelist can defeat the purpose of having protection in the first place.
Don’t avoid using these tools but make sure to observe what happens after you introduce them.
- Deploy the rule.
- Watch the logs.
- Look at blocked requests.
- Look for shared IPs.
- Check origin traffic.
- Check cache hit rates.
- See whether application response times actually improve.
- Then adjust.
- Security configuration shouldn't be treated as a one-time deployment.
Capacity should be the last lever, not the first
When traffic increases, infrastructure upgrades are tempting because they're straightforward. More CPU. More memory. Larger containers. More application instances.
Sometimes that's exactly what a site needs.
But if a significant percentage of the load is coming from automated traffic repeatedly hitting expensive, uncached endpoints, scaling the origin without addressing that traffic is an expensive way to avoid solving the underlying problem.
Before increasing capacity, I would rather answer three questions:
- What is generating the traffic?
- Why is it reaching the application?
- How much of it actually needs to?
Once those questions are answered, infrastructure requirements become much easier to justify.
Back to topThe goal isn't to eliminate bots
Some bots are useful. Some are harmless. Some ignore every instruction you give them. Some deliberately change their behavior to evade detection.
The practical goal is simpler: make automated traffic cheap.
Serve it from cache when possible. Stop obviously abusive behavior at the edge. Protect expensive application endpoints. Keep legitimate users from getting caught in overly aggressive rules. And use actual traffic data to continuously tune those decisions.
A WAF can be a very effective part of that strategy, but the WAF itself isn't the strategy. The best result is not a dashboard showing that you've blocked millions of requests. It's an origin that barely noticed they happened.
Back to top